
Conference · 2026
Multimedia Understanding and SafetyCLARA: Clip-Level Multimodal Alignment with VLM-Derived Rationales for Hateful Video Detection
ACM International Conference on Multimedia (ACM MM)
Abstract
Overview
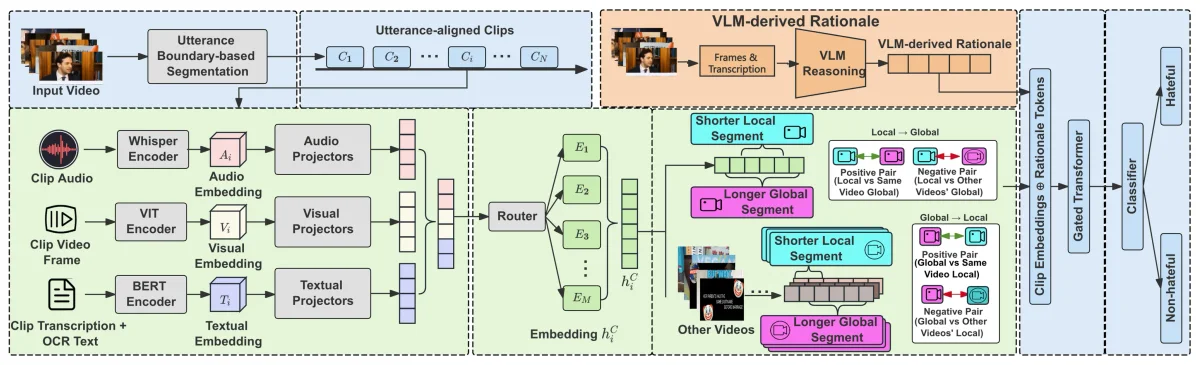
Hateful video detection has become increasingly important with the rapid growth of video-centric social media platforms, given the serious risks that hate speech poses to both individual well-being and social cohesion. Compared with text or static multimodal content, hateful video detection remains underexplored and significantly more challenging, as hateful meaning often arises from complex interactions among multimodal cues, including speech, audio, and visual content. Moreover, such signals are often brief, implicit, and temporally dependent, making them difficult to capture using conventional video-level representations. In this work, we propose CLARA, a clip-level multimodal framework for hateful video detection. Instead of treating a video as a single instance, CLARA models it as a sequence of fine-grained clips, enabling more precise capture of temporally localized hateful signals. We introduce a Mixture-of-Experts clip encoder for adaptive multimodal alignment, a local-global segment contrastive objective to jointly model short-term cues and long-range temporal dependencies, and VLM-derived rationales integrated via a gated Transformer to provide high-level semantic guidance. Extensive experiments on three hateful video datasets demonstrate that CLARA consistently outperforms state-of-the-art methods. Further ablation studies and parameter analyses validate the effectiveness of each component.
Citation
BibTeX
@inproceedings{zhang2026clara,
  title = {CLARA: Clip-Level Multimodal Alignment with VLM-Derived Rationales for Hateful Video Detection},
  author = {Yuchen Zhang and Shuang Dai and Zeyu Fu and Yunfei Long and Ravi Shekhar and Haralambos Mouratidis},
  booktitle = {ACM International Conference on Multimedia (ACM MM)},
  year = {2026},
  eprint = {2608.15905},
  archivePrefix = {arXiv}
}